Architecture of hybrid cloud/edge LLM API integrations
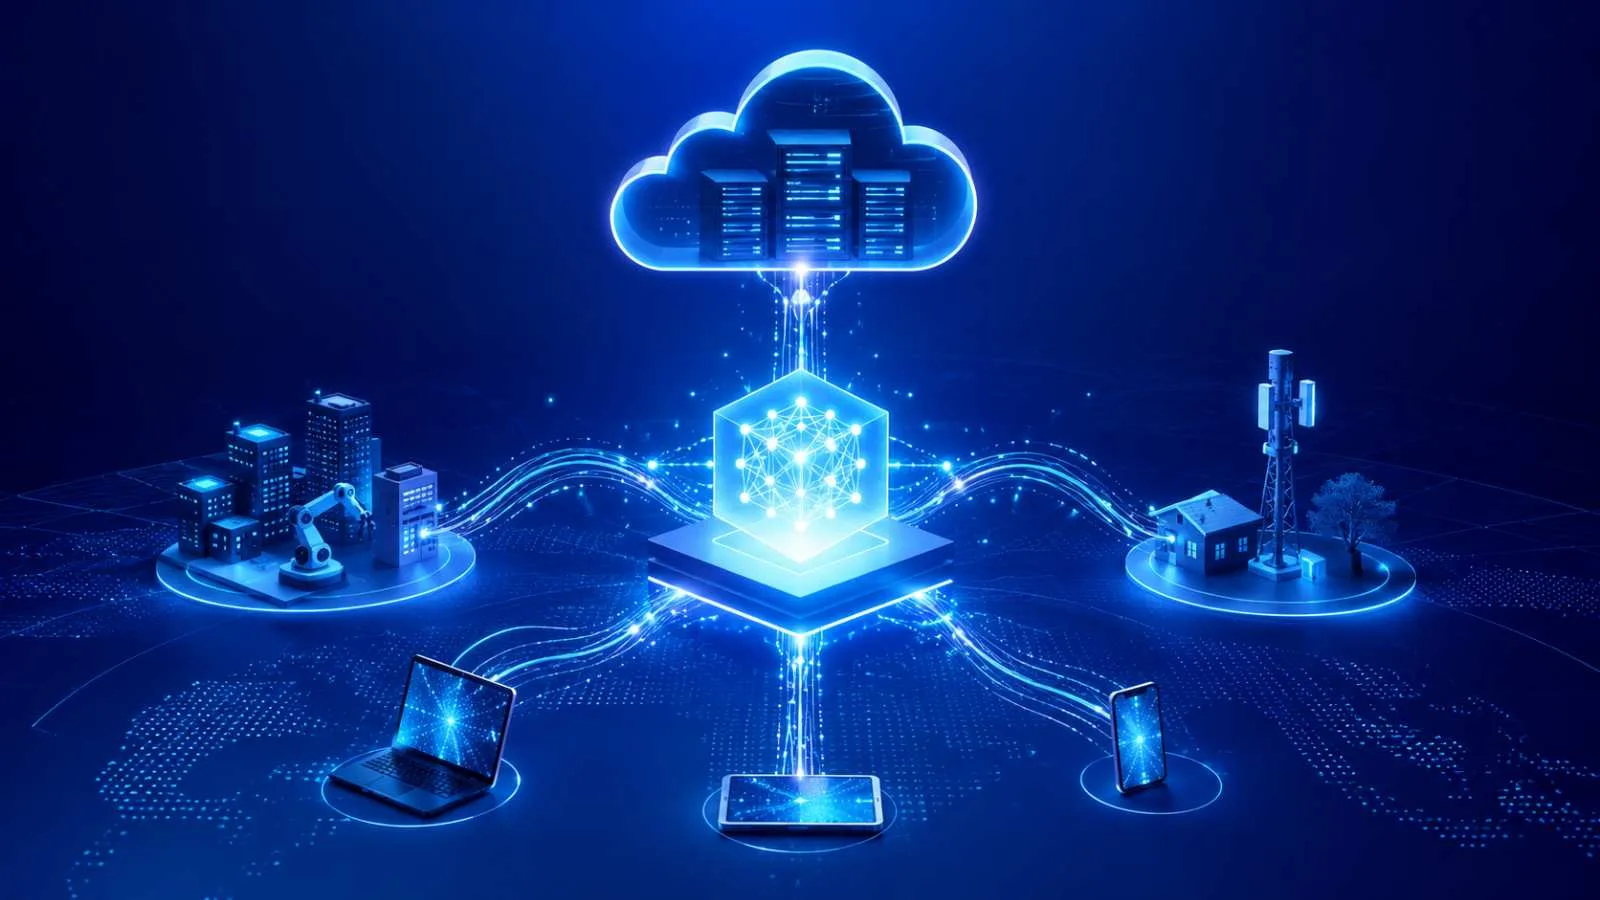
The rise of distributed LLM infrastructures calls for a rigorous setup of traffic flows between local edge environments and external cloud APIs. Within the modern API infrastructure, the LLM gateway acts as the central hub distributing incoming requests based on operational constraints. This article covers the architecture: when does a request run on an edge endpoint and when in the cloud, how do you make that decision based on latency, cost, privacy, and availability, what patterns exist, and what does that complexity cost in terms of observability and configuration.
This article does not cover self-hosting a local inference server; see the documentation on local models behind an API for the fundamentals of local serving. For hardware requirements and sizing of such systems, we refer to the hardware guide for local LLMs as an operational reference. Determining which specific model to deploy falls outside the scope of this architecture document; for that, consult the guide on small on-device models for the current on-device model selection.
The decision matrix: cloud versus edge
Routing requests requires a dynamic evaluation of four pillars: network latency, operational cost, data privacy, and service availability. An edge endpoint is physically close to the user or within the company's own network, often connected via infrastructures as described in the article on local LLMs remotely via Tailscale to guarantee secure connectivity. Public cloud APIs, on the other hand, offer scalability and access to large foundation architectures, but introduce external network dependencies.
Latency-sensitive applications, such as real-time autocomplete or interactive voice assistants, require predictable response times under a hundred milliseconds. Local inference minimizes network time, but the total processing time depends on the compute capacity of the local hardware. For complex reasoning tasks and multimodal analyses, local models often fall short, making the cloud the only viable option. Privacy-sensitive requests containing medical or financial personal data, on the other hand, must stay within national borders or the local network, regardless of the performance differences.
Architecture patterns for routing and failover
To ensure reliability and efficiency, specific patterns are applied within the API gateway. Strategies for determining the right backend and absorbing outages are detailed in the handbook on model routing and fallback mechanisms. Below, the four primary patterns are discussed in detail based on their failure mode, detection, mitigation, and the cost of that mitigation.
Pattern 1: Latency-based routing
This pattern sends requests to the endpoint with the lowest estimated round-trip time (RTT) and processing time. This prevents users on slow networks from getting stuck on heavy cloud connections, or local nodes from becoming overloaded under heavy load.
- Failure mode: A local edge endpoint becomes overloaded by a sudden spike in requests, causing the queue depth to increase exponentially and the Time To First Token (TTFT) to exceed acceptable limits.
- Detection: The API gateway continuously measures RTT and the current per-token processing time via active health checks and trailing measurements of active streams. Once the average response duration over a thirty-second window rises above the two-hundred-millisecond threshold, the node is marked as degraded.
- Mitigation: The gateway automatically switches over to an optimized cloud endpoint with guaranteed SLAs, applying strict timeouts as described in the guidelines for timeouts and cancellation.
- Cost: This mitigation increases operational costs because more expensive cloud tokens are consumed, and it introduces a fixed network latency from the external API provider.
Pattern 2: Privacy-first routing with cloud fallback
This pattern classifies incoming payloads by sensitivity. PII (Personally Identifiable Information) and classified company data may not leave the local perimeter, unless the local infrastructure fails completely and an explicit business emergency has been declared.
- Failure mode: A local model crashes while processing a sensitive prompt, causing the system to enter a deadlock and the API to return an HTTP 500 error to the client.
- Detection: The gateway registers the absence of a valid response stream within the set deadline and checks the heartbeat of the local inference daemon.
- Mitigation: The system automatically performs strict sanitization and anonymization on the prompt to strip all sensitive entities, after which the anonymized request is still sent to the public cloud API.
- Cost: The complexity of the pipeline increases due to the implementation of deterministic PII filtering, which costs extra CPU cycles and carries risks of semantic loss in the prompt.
Pattern 3: Warm/cold endpoints
To limit energy costs and hardware wear, heavy local models often run in a 'cold' or 'standby' state where memory is freed or GPU clocks are lowered. When a request comes in, the model must be loaded.
- Failure mode: Warming up the local model takes longer than the configured client timeout, resulting in the request being aborted prematurely by the client.
- Detection: The gateway registers a client cancellation or a gateway timeout during the model initialization phase in the local VRAM allocation.
- Mitigation: The request is forwarded directly to an already warmed-up cloud endpoint, while the local model in the background stays in cold status until the next peak.
- Cost: This causes unnecessary duplicate resource use and temporary peak load on network bandwidth, in addition to extra costs for the unexpected cloud call.
Pattern 4: Circuit breaker and failover
When an external or local provider fails structurally, the gateway must prevent ongoing requests from being sent to an unreachable endpoint in order to avoid cascading failures.
- Failure mode: The external cloud provider is experiencing a regional outage, causing all API calls to fail with connectivity errors or rate-limit exceptions.
- Detection: The circuit breaker counts the number of consecutive errors (HTTP 429, 502, 503, 504) within a sixty-second time window. Once the threshold of five errors is reached, the state flips from 'closed' to 'open'.
- Mitigation: All incoming requests are immediately redirected to the local edge endpoint or a secondary cloud provider, while the primary backend is temporarily blocked for further attempts.
- Cost: The local edge endpoint can become overloaded by the sudden influx of the total production traffic, leading to increased latency for all users.
When hybrid is not the solution
A hybrid cloud and edge architecture introduces significant operational complexity in terms of routing, state management, and synchronization. For applications with low request volume, this infrastructure doesn't pay off against the benefits. The operational overhead of maintaining local endpoints and failover mechanisms leads to disproportionately high management costs per request in such scenarios.
Strict laws and regulations or sector-specific compliance frameworks can explicitly prohibit processing sensitive data on decentralized edge hardware. When data sovereignty requires that all data stay within a centralized, audited environment, the hybrid model fails because the edge equipment doesn't meet the security certification. Ignoring this restriction results in direct legal non-compliance and potential data breach risk.
Complex workloads that require a very large context window or involve intensive reasoning tasks are usually not feasible locally on edge hardware due to hardware limits in memory and compute power. Forcing such tasks onto under-provisioned edge equipment leads to unacceptable response times or memory overflow. Conversely, applications with a continuous, high volume of simple tasks operate entirely locally to eliminate ongoing cloud transaction costs; introducing a hybrid component here only adds network latency.
Privacy-first and model capacity
Local edge endpoints don't always have a model with the right capacity or type to perform a specific task. When a request requires a complexity or modality that exceeds the local model, the gateway may not automatically forward the data to the cloud if that would violate the privacy policy. The architecture then requires an explicit, structured rejection that is returned directly to the client.
Such a rejection has a negative impact on the user experience, because the client application fails instead of receiving a fallback answer. To manage this, the system closely monitors the number of rejections via specific error counters in the gateway. This type of measurement makes it possible to analyze patterns in model capacity and adjust local model selection in a targeted way, without making concessions to the privacy framework in place.
Provider-independent pseudocode for routing
The code snippet below demonstrates a provider-independent implementation of a routing algorithm with built-in timeout handling, fallback logic, and error isolation.
import time
import requests

def route_and_execute_request(prompt, metadata, config):
    start_time = time.time()
    endpoint = select_optimal_backend(metadata, config)

    timeout_budget = config.get("max_timeout_ms", 5000) / 1000.0
    elapsed = time.time() - start_time
    remaining_timeout = max(0.1, timeout_budget - elapsed)

    try:
        response = execute_inference_call(endpoint, prompt, timeout=remaining_timeout)
        return response
    except (requests.Timeout, ConnectionError) as e:
        log_routing_failure(endpoint, e)
        fallback_endpoint = get_fallback_backend(endpoint, config)

        fallback_elapsed = time.time() - start_time
        fallback_remaining = max(0.1, timeout_budget - fallback_elapsed)

        try:
            fallback_response = execute_inference_call(fallback_endpoint, prompt, timeout=fallback_remaining)
            return fallback_response
        except Exception as fallback_error:
            log_critical_failure(fallback_endpoint, fallback_error)
            raise RuntimeError("Alle inferentie-backends gefaald binnen het tijdslimiet.") from fallback_error
    except Exception as unexpected_error:
        log_unexpected_error(endpoint, unexpected_error)
        raise unexpected_error

def select_optimal_backend(metadata, config):
    if metadata.get("is_pii_present", False):
        return config["edge_endpoint"]
    if metadata.get("latency_critical", False) and config["edge_latency_ms"] < config["cloud_latency_ms"]:
        return config["edge_endpoint"]
    return config["cloud_endpoint"]

def get_fallback_backend(failed_endpoint, config):
    if failed_endpoint == config["edge_endpoint"]:
        return config["cloud_endpoint"]
    return config["edge_endpoint"]

def execute_inference_call(endpoint, prompt, timeout):
    payload = {"prompt": prompt}
    response = requests.post(endpoint["url"], json=payload, timeout=timeout)
    if response.status_code != 200:
        raise requests.HTTPError(f"API retourneerde statuscode {response.status_code}")
    return response.json()

def log_routing_failure(endpoint, error):
    pass

def log_critical_failure(endpoint, error):
    pass

def log_unexpected_error(endpoint, error):
    pass
Observability and configuration management
Introducing hybrid routing significantly increases operational complexity. Measuring the effectiveness of the chosen routes requires detailed telemetry at the gateway level. For setting up these measurements and analyzing errors per route, we refer to the technical guide on observability and logging.
Metrics for a hybrid route
Continuously monitoring performance per route is necessary to keep the routing logic in the hybrid architecture functioning optimally. The table below shows the critical operational metrics, the associated goals, and the illustrative thresholds for intervention.
| Metric | Purpose | Threshold (illustrative) |
|---|---|---|
| TTFT per route | Minimizing the time-to-first-token per endpoint | < 200 ms (edge), < 800 ms (cloud) |
| Error ratio per route | Detecting degradation or outages per infrastructure | < 1.0% of the total number of requests |
| Cost per route | Monitoring the budget per processed token | Set maximum per million tokens |
| Circuit breaker status | Monitoring the operational health of the fallback | Closed (opens at > 5 consecutive failures) |
| Edge/cloud request ratio | Optimizing capacity distribution | At least 70% processed locally |
Every decision made by the router — whether a request is sent to the edge or the cloud — must be logged including the deterministic reason (latency, privacy, cost, or fallback). Without this detailed tracing, it is impossible to trace performance degradations in distributed architectures. Configuration management must also be handled dynamically via centralized feature flags or service meshes, so that thresholds for RTT and error rates can be adjusted without having to redeploy the API gateway.
The complexity manifests directly in the management burden: network partitions between the cloud and local nodes, asynchronous synchronization of model versions, and discrepancies in output formats between different inference servers require continuous monitoring. By applying strict timeouts, circuit breakers, and structured fallbacks, the availability of the overall API infrastructure remains guaranteed, regardless of incidents on the backend side.
Checklist for a hybrid setup
- Implement latency-based routing including hysteresis to prevent oscillation between routes.
- Activate automatic PII detection and masking before any cloud routing takes place.
- Configure an explicit, structured rejection for when local model capacity is insufficient and cloud routing is excluded.
- Install a circuit breaker on the fallback route to prevent overloading the secondary infrastructure.
- Use a token bucket algorithm to monitor the hard limits of the cloud API.
- Maintain keep-alive connections to minimize the startup time for warm endpoints.
- Collect and segment operational metrics per individual route for accurate analysis.
- Run periodic failover tests under conditions of artificial latency and network disruptions.
- Clearly define the functional boundary with the article on self-hosting models locally.